The answer reports the two expected prices as competing evidence, using conflict language or citations to both sides.
EXPERIMENT E001 / UPDATED 05 AUG 2026
Do models notice when menu prices disagree?
We tested 13 vision models from OpenAI and Fireworks on the same questions and retrieved images. Each model answered once with an instruction to report disagreements between images, and once with only the price question. Every answer on this page is scored by the same automatic classifier with no post-hoc overrides.
- Questions
- 50
- Models
- 13
- Ways tested
- 2
- Model answers
- 1,300
- Images per answer
- 6
01 / HOW ANSWERS ARE SCORED
Every answer goes into one of six groups
The answer returns exactly one price without reporting a disagreement.
The response explicitly says it cannot determine the answer, the evidence is insufficient, or the relevant text is unreadable.
The response contains usable text but does not satisfy the strict rules for either reporting both prices or returning one price.
The provider stopped at the output-token limit before returning a final answer. Reasoning text is retained but receives no answer credit.
The request fails or repeatedly returns no usable text.
These are automatic labels, not human judgments. The same classifier is applied to all 1,300 answers.
02 / DID RETRIEVAL FIND THE RIGHT IMAGES?
Both menu versions appeared for 45 of 50 questions
For each question, the system first selected that restaurant's images, then ranked them by image similarity and returned the top six.
The other five questions remain in the end-to-end totals. The expected original or edited image was never injected after retrieval.
03 / ALL 13 MODELS / BOTH VERSIONS RETRIEVED
One combined comparison
Forty-five successful retrieval cases across 13 models: 585 answers in each instruction condition.
31.8%Gave both prices186 / 585
41.2%Gave one price241 / 585
1.9%Said evidence was insufficient11 / 585
25.1%Ambiguous or unclassified147 / 585
15.2%Gave both prices89 / 585
70.1%Gave one price410 / 585
2.7%Said evidence was insufficient16 / 585
12.0%Ambiguous or unclassified70 / 585
Combined result
When explicitly instructed to report disagreements, the 13 models gave both prices in 186 of 585 answers. When asked only for the item price, they did so in 89 of 585 answers.
04 / EVERY MODEL / SAME AUTOMATIC SCORING
What each model did when both versions were available
Every row uses the same 45 questions and the same classifier. Provider is shown only as model provenance.
| Model | Price question + instruction to report disagreements | Price question only | ||||||
|---|---|---|---|---|---|---|---|---|
| Reported both prices | Returned one price | Said evidence was insufficient | Ambiguous / unclassified | Reported both prices | Returned one price | Said evidence was insufficient | Ambiguous / unclassified | |
| Kimi K2.7 Code Fireworks | 21 / 45 | 10 / 45 | 2 / 45 | 12 / 45 | 20 / 45 | 17 / 45 | 1 / 45 | 7 / 45 |
| GPT-5.4 OpenAI | 19 / 45 | 12 / 45 | 0 / 45 | 14 / 45 | 16 / 45 | 21 / 45 | 0 / 45 | 8 / 45 |
| Kimi K3 Fireworks | 19 / 45 | 11 / 45 | 1 / 45 | 14 / 45 | 5 / 45 | 32 / 45 | 1 / 45 | 7 / 45 |
| GPT-5.5 OpenAI | 17 / 45 | 16 / 45 | 0 / 45 | 12 / 45 | 4 / 45 | 33 / 45 | 0 / 45 | 8 / 45 |
| GPT-5.6 Luna OpenAI | 17 / 45 | 22 / 45 | 0 / 45 | 6 / 45 | 6 / 45 | 37 / 45 | 0 / 45 | 2 / 45 |
| GPT-5 OpenAI | 15 / 45 | 23 / 45 | 5 / 45 | 2 / 45 | 4 / 45 | 37 / 45 | 3 / 45 | 1 / 45 |
| Qwen3.7 Plus Fireworks | 15 / 45 | 7 / 45 | 1 / 45 | 22 / 45 | 15 / 45 | 12 / 45 | 1 / 45 | 17 / 45 |
| GPT-5.6 Sol OpenAI | 14 / 45 | 26 / 45 | 0 / 45 | 5 / 45 | 0 / 45 | 43 / 45 | 0 / 45 | 2 / 45 |
| Kimi K2.6 Fireworks | 12 / 45 | 12 / 45 | 2 / 45 | 19 / 45 | 10 / 45 | 22 / 45 | 7 / 45 | 6 / 45 |
| GPT-4.1 OpenAI | 12 / 45 | 20 / 45 | 0 / 45 | 13 / 45 | 1 / 45 | 41 / 45 | 2 / 45 | 1 / 45 |
| GPT-4o OpenAI | 10 / 45 | 24 / 45 | 0 / 45 | 11 / 45 | 1 / 45 | 42 / 45 | 0 / 45 | 2 / 45 |
| GPT-5.6 Terra OpenAI | 9 / 45 | 33 / 45 | 0 / 45 | 3 / 45 | 3 / 45 | 40 / 45 | 0 / 45 | 2 / 45 |
| Inkling Fireworks | 6 / 45 | 25 / 45 | 0 / 45 | 14 / 45 | 4 / 45 | 33 / 45 | 1 / 45 | 7 / 45 |
These results cover 45 questions per model and prompt setting. “Said evidence was insufficient” is detected from explicit inability language; all remaining unmatched responses are shown separately as ambiguous or unclassified.
05 / ORIGINAL YELP SOURCE IMAGE
Performance varies sharply by source photo
Ordered by pixel count, from the lowest-resolution source upward.
| Original Yelp image | Pixel resolution | Both versions retrieved | Prompt: report disagreements | Prompt: price only |
|---|---|---|---|---|
 source_08 |
243 × 400 0.10 MP | 5 / 5 | 15 / 65 both (23.1%)35 one · 0 insufficient · 15 ambiguous | 3 / 65 both (4.6%)60 one · 0 insufficient · 2 ambiguous |
 source_09 |
300 × 400 0.12 MP | 5 / 5 | 8 / 65 both (12.3%)37 one · 4 insufficient · 16 ambiguous | 2 / 65 both (3.1%)51 one · 7 insufficient · 5 ambiguous |
 source_02 |
309 × 400 0.12 MP | 5 / 5 | 9 / 65 both (13.8%)25 one · 0 insufficient · 31 ambiguous | 6 / 65 both (9.2%)37 one · 0 insufficient · 22 ambiguous |
 source_10 |
346 × 400 0.14 MP | 5 / 5 | 29 / 65 both (44.6%)18 one · 0 insufficient · 18 ambiguous | 17 / 65 both (26.2%)39 one · 1 insufficient · 8 ambiguous |
 source_05 |
600 × 290 0.17 MP | 5 / 5 | 0 / 65 both (0.0%)59 one · 3 insufficient · 3 ambiguous | 0 / 65 both (0.0%)59 one · 2 insufficient · 4 ambiguous |
 source_01 |
600 × 334 0.20 MP | 5 / 5 | 47 / 65 both (72.3%)16 one · 0 insufficient · 2 ambiguous | 26 / 65 both (40.0%)38 one · 0 insufficient · 1 ambiguous |
 source_04 |
600 × 337 0.20 MP | 1 / 5 | 3 / 13 both (23.1%)7 one · 0 insufficient · 3 ambiguous | 0 / 13 both (0.0%)12 one · 1 insufficient · 0 ambiguous |
 source_03 |
533 × 400 0.21 MP | 5 / 5 | 17 / 65 both (26.2%)16 one · 2 insufficient · 30 ambiguous | 5 / 65 both (7.7%)39 one · 3 insufficient · 18 ambiguous |
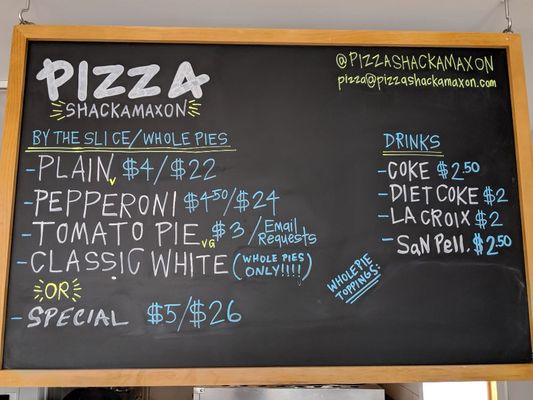 source_06 |
533 × 400 0.21 MP | 5 / 5 | 56 / 65 both (86.2%)6 one · 0 insufficient · 3 ambiguous | 30 / 65 both (46.2%)34 one · 0 insufficient · 1 ambiguous |
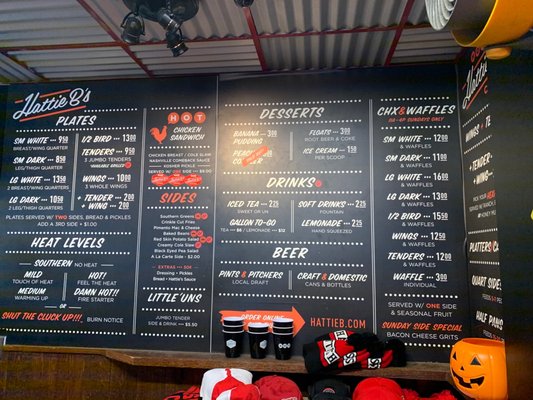 source_07 |
533 × 400 0.21 MP | 4 / 5 | 2 / 52 both (3.8%)22 one · 2 insufficient · 26 ambiguous | 0 / 52 both (0.0%)41 one · 2 insufficient · 9 ambiguous |
Source-image finding
Resolution is not the only difficulty factor. Under the disagreement-reporting prompt, source-level both-price rates range from 0.0% to 86.2%; even the three 533 × 400 images range from 3.8% to 86.2%.
06 / ALL 50 QUESTIONS / ALL 13 MODELS
End-to-end results including retrieval failures
Six hundred fifty answers in each instruction condition.
- Gave both prices
- 186 / 650 28.62%
- Gave one price
- 274 / 650 42.15%
- Said evidence was insufficient
- 13 / 650 2.00%
- Ambiguous or unclassified
- 177 / 650 27.23%
- Incomplete generation
- 0 / 650
- Error
- 0 / 650
- Gave both prices
- 89 / 650 13.69%
- Gave one price
- 445 / 650 68.46%
- Said evidence was insufficient
- 21 / 650 3.23%
- Ambiguous or unclassified
- 95 / 650 14.62%
- Incomplete generation
- 0 / 650
- Error
- 0 / 650
07 / WHAT THIS MEANS
Restaurant scoping fixes most retrieval failures, but models still collapse conflicting prices
Across all 13 models, reporting both prices increased when the prompt explicitly instructed models to report disagreements between the retrieved images. Restaurant filtering raised retrieval of both expected versions from six to 45 questions, yet models still returned only one price in many cases where both versions were available. These results use one common automatic scoring process; no model receives post-hoc label corrections.